OFFSHORE DATA ANNOTATOR STAFFING
BUILD YOUR LABELING TEAM WITHOUT THE HIRING GRIND
Trained annotators, real QA, no platform queue between you and your data
We place dedicated offshore data annotators who label images, text, and audio for your AI models, trained on your taxonomy and reviewed by your team, at a fraction of what a US-based labeling hire costs.
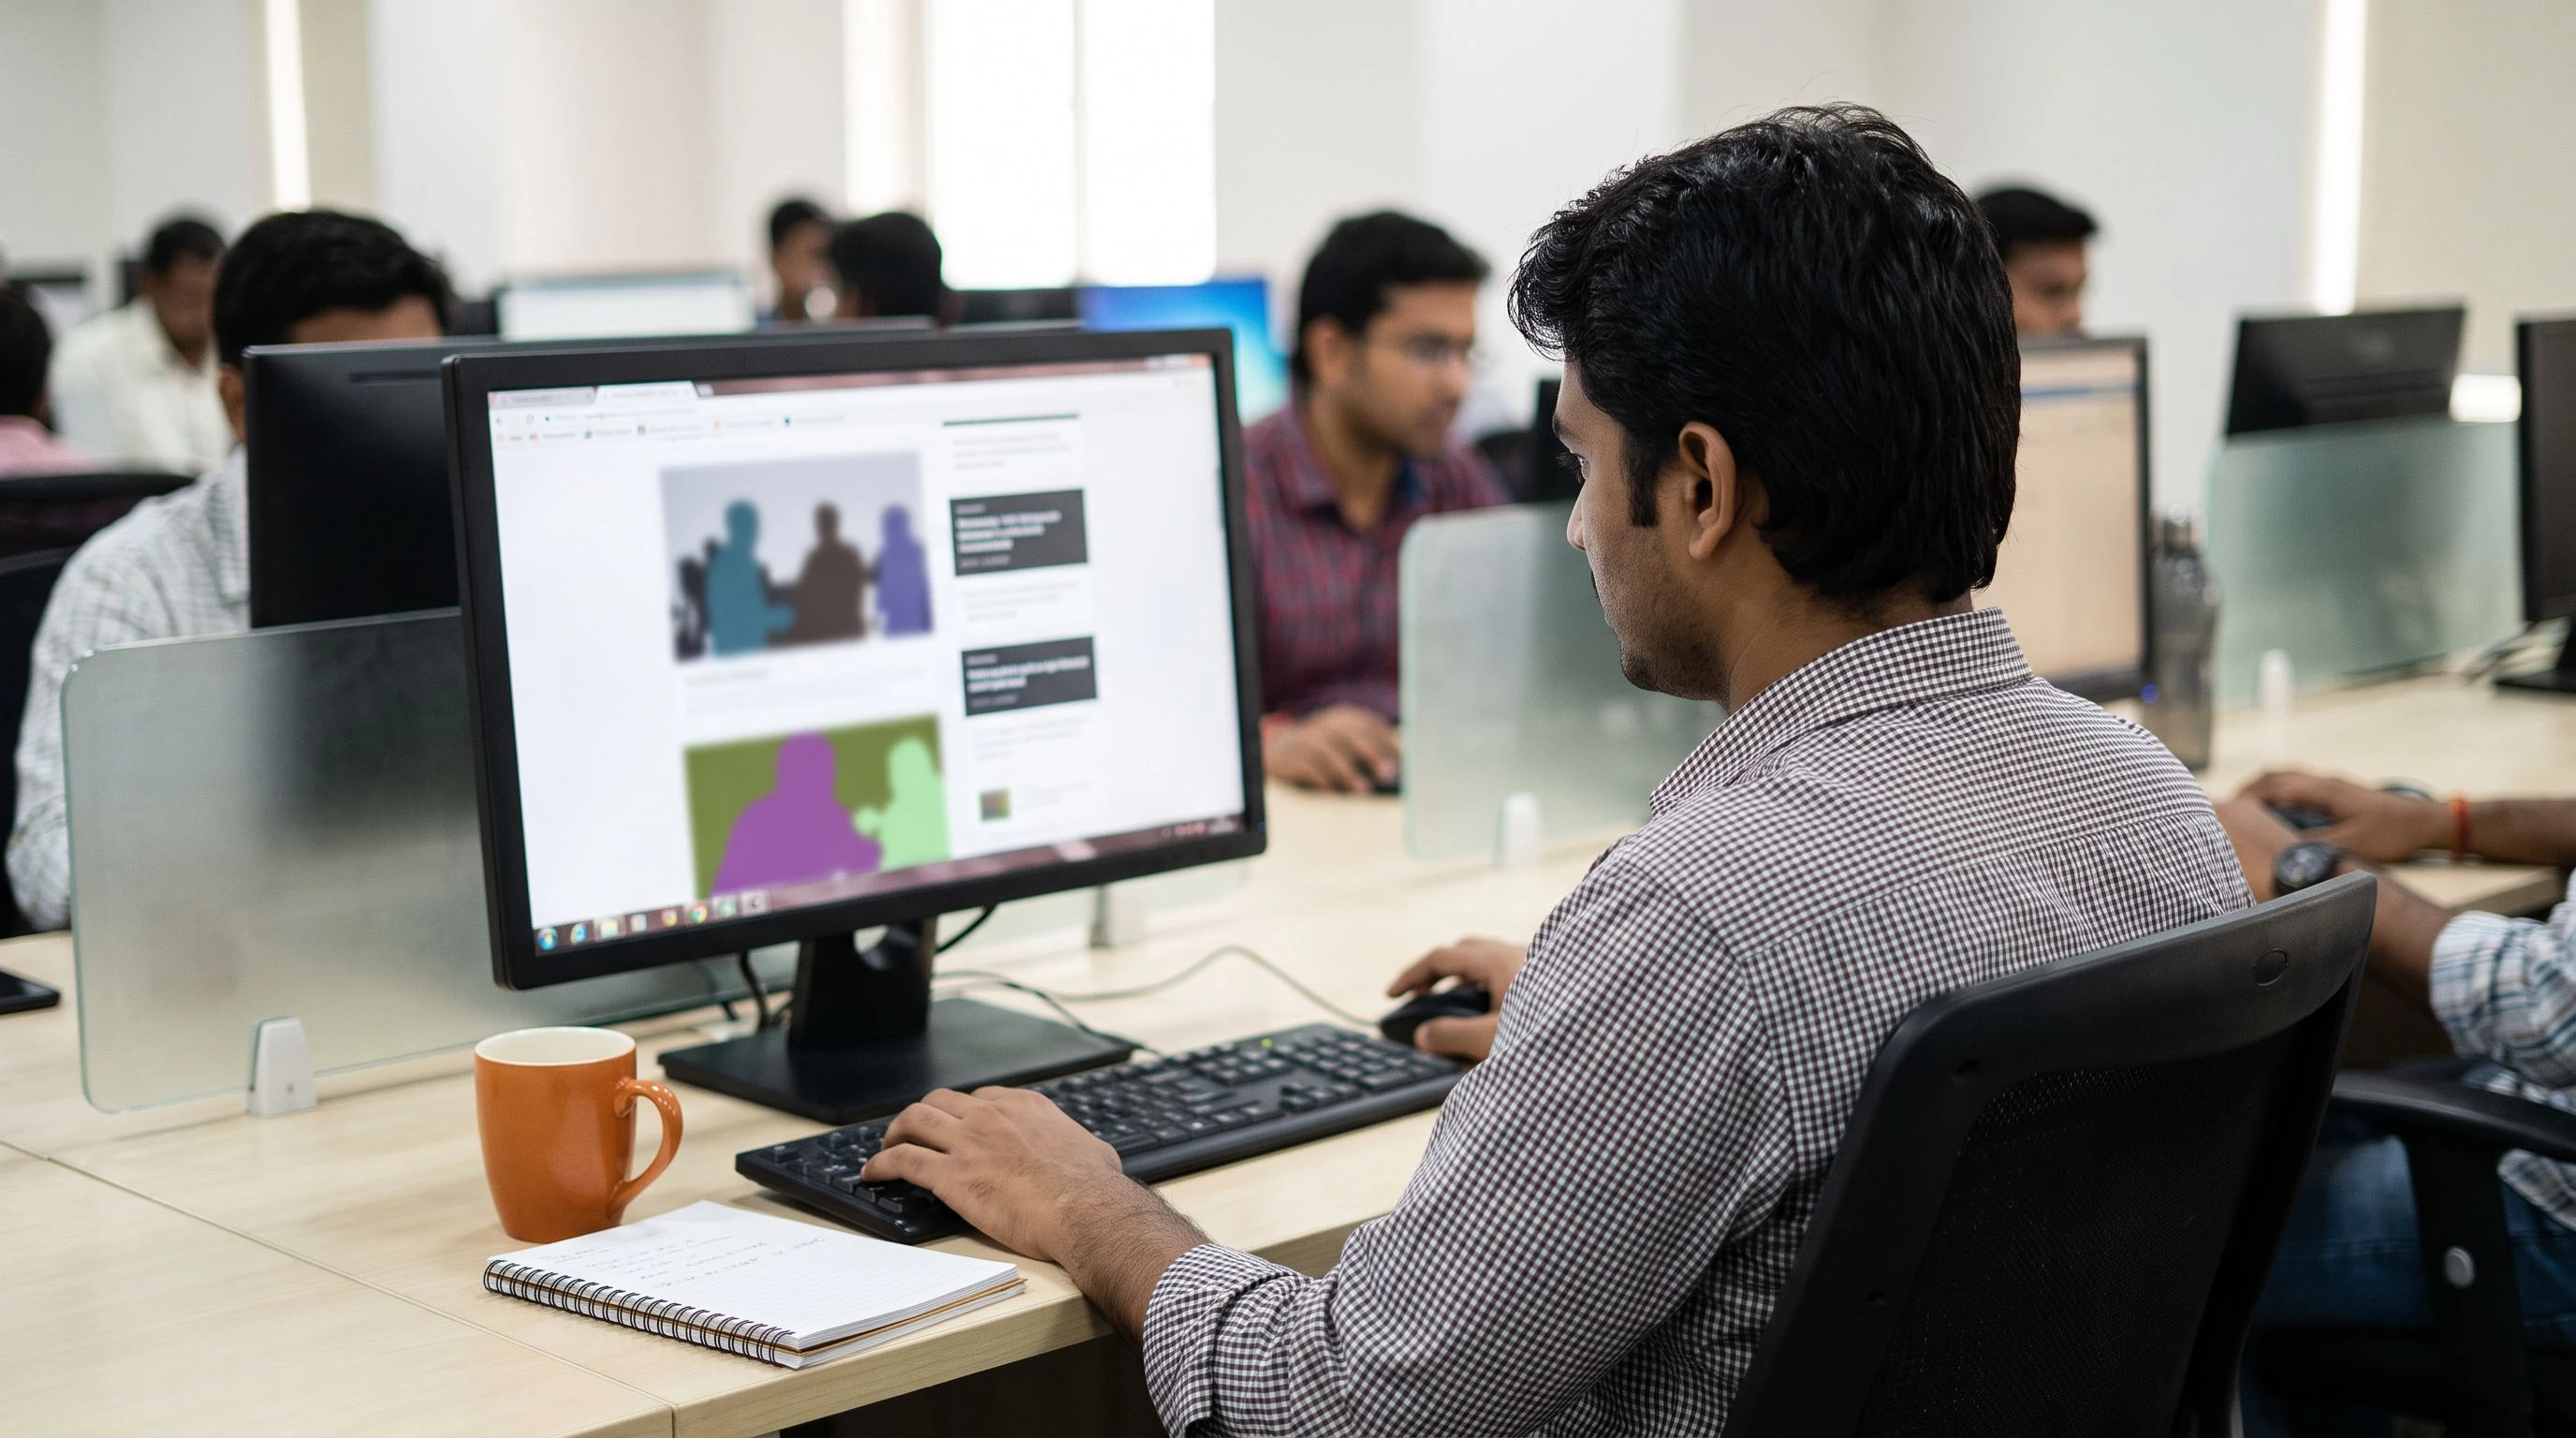
Hiring an offshore data annotator means placing a trained labeling specialist, usually based in India, who tags images, text, audio, or video so your AI model has clean data to learn from, typically at 60–75% below US labeling costs. Kore BPO screens, places, and supervises the handoff so your model's ground truth doesn't depend on whoever happened to answer a gig-platform job post that week.
Somewhere right now, a machine learning team is staring at a backlog of 80,000 unlabeled frames and a model deadline that doesn't care how that backlog got there. That's the job an offshore data annotator exists to solve. Not glamorous work. Necessary work. Every computer vision model, every chatbot, every fraud detector started as a pile of raw data that somebody had to tag, correct, and tag again.
This page is the hub for Kore BPO's offshore data annotator cluster. Below, you'll find the role definition, the real tools these annotators use, screening steps, pay data, and links out to deeper guides on pricing, job descriptions, and how this role stacks up against building the function in-house.
What a Data Annotator Actually Does
Three roles get lumped together constantly, and the mix-up wastes hiring budget. Here's the actual split.
A specialist who applies labels, tags, or bounding boxes to raw data (images, text, audio) so a machine learning model can learn from it, following a defined taxonomy and accuracy standard. The work is tactical and repetitive by design, consistency matters more than creativity, and a good annotator is judged on inter-annotator agreement scores, not output volume alone.
- Data labeler is mostly a synonym. Some teams use it for simpler, high-volume tagging work and reserve "annotator" for tasks needing more judgment, like medical image review.
- Data engineer builds the pipelines that move and store data. They don't touch the labeling itself.
- ML engineer trains and tunes the model that consumes the labels. Garbage labels, garbage model, no matter how good the engineer is.
Demand Is Outrunning the Supply of Trained Annotators
Every model release cycle creates a new wave of labeling demand, and the market numbers back that up. Research and Markets pegs the global AI annotation market at $2.51 billion in 2026, growing to $7.32 billion by 2030, a 30.7% compound annual growth rate. That's not a slow category. India has positioned itself as the labeling hub for that growth, and the scale is hard to overstate: NASSCOM projects India's data annotation services market could exceed $7 billion by 2030, up from roughly $250 million in FY20, supporting a workforce that could approach one million workers. One million. For a job category most hiring managers couldn't define three years ago.
Time-to-fill is where this gets practical. US-based annotation hires are scarce and expensive relative to the work, while India's talent pool is deep but scattered across thousands of gig platforms, agencies, and freelancers of wildly uneven quality. Kore BPO's own placement data shows resumes landing in 2–5 business days once a scope call happens, which beats the usual 3–6 week slog of posting, screening, and re-posting a labeling role on a general job board.
Tools and Annotation Types Your Annotator Should Know
We screen for specific tool fluency, not a vague "comfortable with tech" checkbox. Here's the breakdown by category.
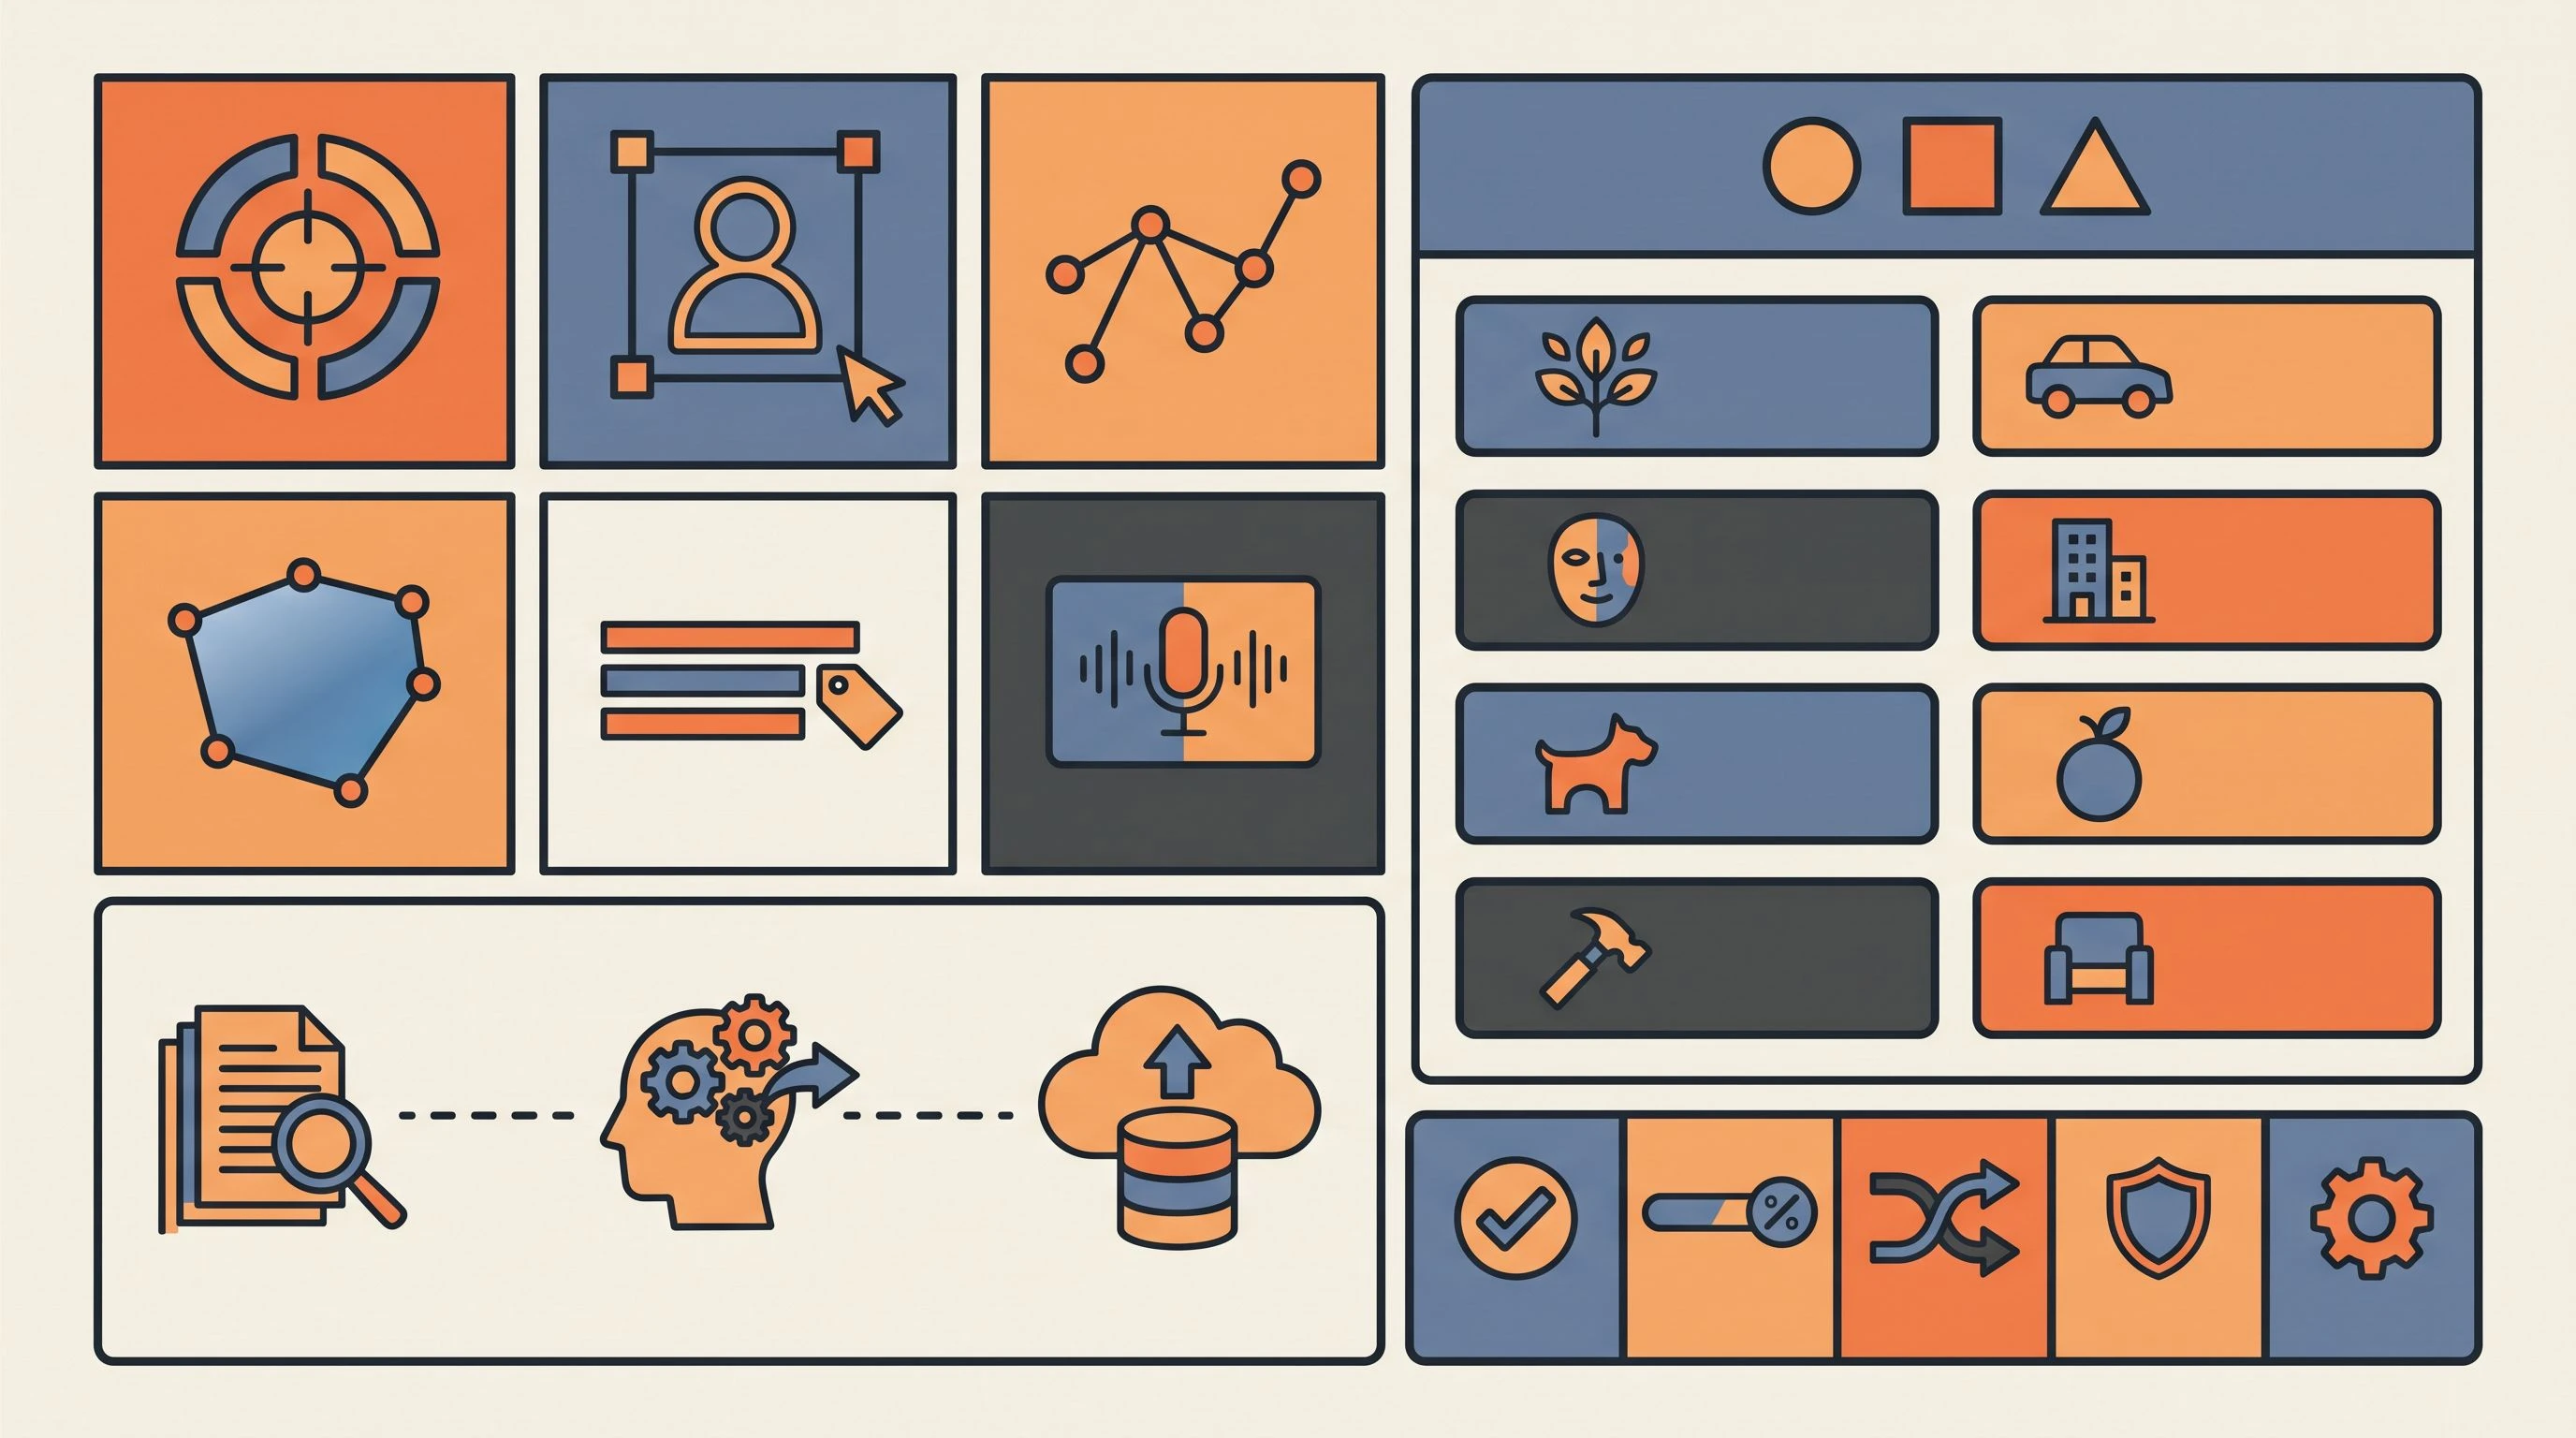
Labelbox, CVAT, SuperAnnotate, and similar annotation tooling for project setup, label review, and export pipelines
Bounding boxes, polygon and instance segmentation, keypoint and pose labeling, 3D cuboid annotation for sensor data
Named entity tagging, intent classification, sentiment labeling, and transcript annotation for chatbot and search models
Response ranking, preference pair labeling, and instruction-following evaluation for reinforcement learning from human feedback
Transcription QA, speaker diarization labeling, and intent tagging for voice assistant and call center model training
Inter-annotator agreement review, gold-standard set calibration, and edge-case escalation to a lead reviewer
Where Teams Actually Use This Role
You're training a defect-detection model and need 50,000 labeled factory-line images in three weeks, with bounding boxes on every flaw type your QA team cares about.
Your chatbot keeps giving confident wrong answers, and you need a team ranking thousands of response pairs for an RLHF fine-tuning pass before the next release.
User-generated content volume tripled after a product launch, and your trust and safety model needs a steady stream of freshly tagged edge cases to stay accurate.
Sensor and LiDAR data from a pilot fleet is piling up untouched, and your perception model can't improve until someone cuboids every pedestrian and vehicle in the set.
Query intent classification accuracy plateaued, and you suspect the training set itself has inconsistent labels nobody has audited since the model's first version.
Five Checks Before You Ever See a Resume
Annotation work lives or dies on consistency. Our screening is built around catching the annotators who drift from the standard, before your model ever sees their work.
Candidates label a sample set against a known gold standard, scored on precision, not speed.
Hands-on test in Labelbox, CVAT, or SuperAnnotate to confirm real platform fluency, not resume buzzwords.
Inter-annotator agreement measured across a repeated sample to catch drift before it reaches you.
English proficiency and ability to follow a written taxonomy exactly, without improvising edge cases.
A short paid trial on your actual data, under your NDA, before any long-term placement decision.
What Data Annotators Actually Get Paid
Numbers below reflect current market pay, not Kore BPO's placement pricing. For the full staffing cost breakdown, see the dedicated pricing guide.
| Level | India Market, Annual | India Market, Monthly Equiv. | Source |
|---|---|---|---|
| Entry (0–2 yrs) | ₹2,32,000–3,07,000 | roughly $230–$310 | Glassdoor India, Feb 2026 |
| Mid / Specialized (3+ yrs, complex QA or RLHF) | ₹5,00,000–7,20,000 | roughly $500–$720 | Glassdoor India, Feb 2026 (75th pctl) |
| US comparison, generalist annotator | $60,476 | $5,040 ($29/hr) | Glassdoor US, Oct 2026 |
Figures above are local market salary data, not a bill rate. Actual pay and Kore BPO's placement pricing both vary by location, annotation complexity, required tooling, and project volume. India figures are sparse and inconsistent across sources, treat the range as directional.
Here's the blunt version. A US generalist annotator costs roughly 8–20 times what the same work costs loaded into an India-based hire, even before benefits and overhead get added to the US number. That gap is exactly why the offshore model exists for this role, and exactly why it won't exist forever if AI eventually automates the simpler labeling tiers. For now, judgment calls on edge cases still need a human.
Annotation Work Rarely Fits a Full-Time Mold
Data annotation work typically comes in bursts tied to a specific model training cycle, not a steady year-round headcount need. That's why this role skews heavily toward contract and project-based engagement rather than the contract-to-hire pattern common in software roles.
- Short-burst projects, like a 50,000-image labeling sprint, fit project-based pricing best
- Ongoing moderation or RLHF pipelines usually justify a dedicated monthly contract annotator
- Contract-to-hire works when you expect labeling volume to stay high long-term
- No upfront fees on any of the three models, you pay for placed work, not a search retainer
Who This Is For, and Who It Isn't
Full disclosure, we're a staffing company. If you're only labeling a few hundred images a month, you probably don't need a dedicated hire at all, and we'll tell you that on the scope call.
Have an active model training pipeline, a defined (or roughly defined) labeling taxonomy, and recurring or burst-level volume above a few thousand items a month.
You need one-off, hundred-item labeling jobs, you lack any taxonomy or labeling guide yet, or you want someone to also build your model, that's a different role entirely.
The Questions Hiring Managers Ask Before They Commit
Pick the Model That Matches Your Labeling Volume
Fixed scope, fixed timeline. Best for a single model training sprint with a clear label count and deadline.
A named annotator working your taxonomy full-time, month to month, for ongoing pipelines like moderation or RLHF.
Start on contract, convert once labeling volume proves out as a permanent part of your data operation.
Everything You Need to Hire This Role Right
Guides, pricing data, and templates for hiring an offshore data annotator the right way.
A step-by-step guide to scoping, screening, and onboarding one.
Read the GuideReal 2026 rate ranges by experience level and what drives the cost.
See the PricingAn offshore-ready JD with duties, tools, and QA expectations built in.
Get the TemplateA side-by-side look at cost, speed, and control for each model.
Compare the OptionsWhat Hiring Managers Ask First
What is a data annotator? +
A data annotator labels raw data like images, text, or audio so a machine learning model can learn patterns from it. The work follows a defined taxonomy and accuracy standard set by your ML team, and quality gets measured through inter-annotator agreement, not speed alone.
How much does an offshore data annotator cost compared to hiring in the US? +
India-based annotators typically earn ₹2,32,000–3,07,000 a year at entry level, per Glassdoor India, February 2026, versus a US average of $60,476 for a generalist role, per Glassdoor US, October 2026. The gap is wide enough that most teams see savings even after accounting for management overhead.
Can one annotator handle multiple annotation types? +
Yes, within reason. A generalist can usually move between bounding boxes, basic NLP tagging, and simple QA review. Specialized work like RLHF preference ranking or medical image annotation needs someone screened specifically for that complexity level.
How fast can I get an offshore data annotator in place? +
After a scope call covering your taxonomy, tools, and volume, Kore BPO typically delivers 2–3 pre-vetted candidate profiles within 2–5 business days. Most teams interview, run a paid trial batch, and onboard within two to three weeks total.
Do I need a finished labeling taxonomy before I hire? +
A rough draft is enough to start. Most taxonomies get refined in the first two weeks once an experienced annotator starts flagging the edge cases your draft guidelines missed. Walking in with zero guidance at all does slow the ramp-up down, though.
What's the difference between a data annotator and a data labeler? +
Mostly terminology. Teams that use "labeler" tend to mean high-volume, lower-judgment tagging, while "annotator" sometimes implies tasks needing more context, like review of ambiguous medical or legal content. In practice, the titles overlap more than they differ, and screening criteria matter more than the label on the job post.
Will AI eventually replace this role? +
Auto-labeling tools already handle a growing share of the simple, repetitive tier of this work. Judgment-heavy tasks, ambiguous edge cases, and quality review still need a trained human for the foreseeable future, which is exactly where our placements focus.
What Teams Say
“Partnering with Kore BPO was a game-changer for our marketing efforts. Thanks to their support, we’ve streamlined our operations and seen measurable growth.”
“Kore BPO has been instrumental in helping us streamline our data processes. We’ve been able to free up valuable time to focus on building strong relationships.”
“Kore BPO helped us grow our team faster than we thought possible, without the stress we expected from offshore hiring. The results were transformative.”
Stop Letting Your Backlog Train Your Timeline
Every week your data sits unlabeled is a week your model doesn't improve. Pre-vetted annotators, no upfront fees, resumes in 2–5 business days.
Start Building Your Labeling Team